PDF to Word without losing formatting: what survives
You convert a PDF to Word and the table comes out crooked. You assume the converter is bad, try another one, and get much the same. Some problems do not go away by changing tools.

Understanding why tells you which tool to pick and how much to expect from it.
A PDF only stores the printed page
What sits inside a PDF is a long list of instructions saying print this character at x 72, y 680. Nowhere in the file is it recorded where a paragraph ended, or which two lines belonged to the same row of a table.
That information is thrown away the moment a document is exported to PDF, in the same way a sheet of paper has no need of it. So turning one back means inferring the original shape from where the characters sit.
That single sentence explains the rest. A table comes out crooked because there was no table to read, and one had to be inferred from position alone.
What can be inferred and what was never there
Separating these two tells you what can improve and what cannot.
- Inferable. Paragraph breaks, from line spacing and where lines stop. Tables, from whether cells line up down the page. Headings, from type larger than the body. Better algorithms make these more accurate.
- Directly extractable. The characters themselves, and any images or stamps printed on the page. These are real objects in the file and need no guessing.
- Never recorded. Which Word style the original used, where a table had merged cells, how many points of spacing sat between paragraphs. No tool can produce these.
Be wary of converters that reproduce the layout exactly
Some tools advertise output that matches the original pixel for pixel. Open the result and it genuinely does. Then you edit one line and the document collapses.
Achieving that means putting the text into hundreds of floating text boxes pinned to fixed coordinates rather than into paragraphs. A document built that way looks like the original but cannot be worked in. Delete a character and only that one box reflows while everything around it stays put.
| What you need | What to choose |
|---|---|
| To read and edit the contents | A converter that rebuilds paragraphs |
| Only to read it | Do not convert; use a PDF viewer |
| To match the printout exactly | Do not convert; keep the PDF |
| To calculate with the numbers | Convert to a spreadsheet |
Conversion exists so that you can edit. Output you cannot edit has lost the point. If looking identical is the goal, there was no reason to convert in the first place.
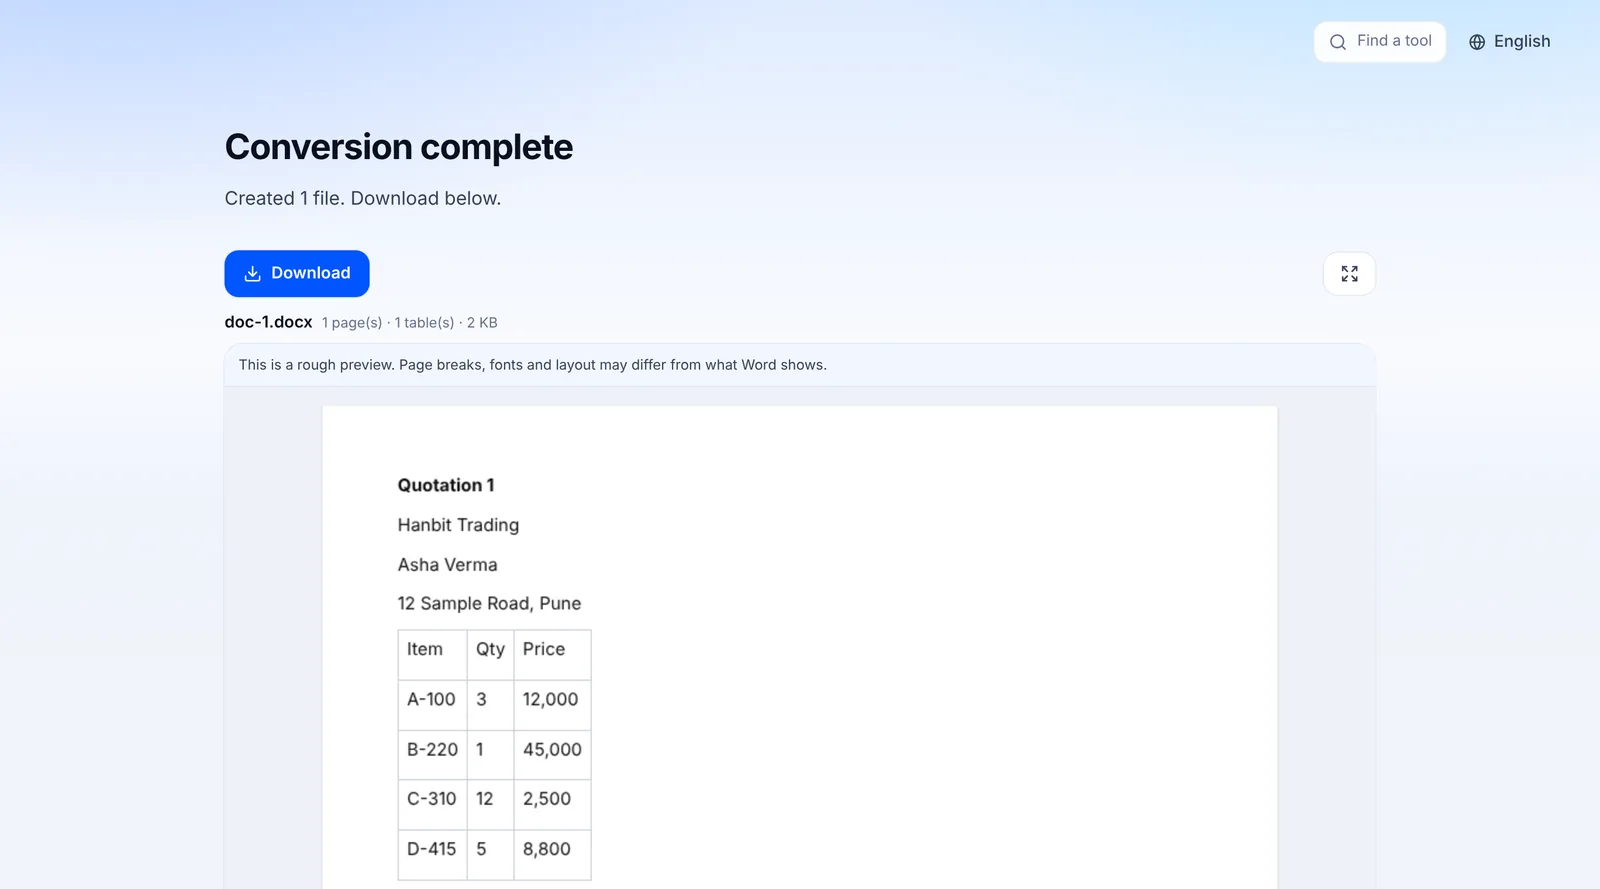
A typical case: a resume or a form someone sent as PDF
In India the PDF you want to edit is very often a document someone else made. A friend's resume you want to reuse as a template. A college or office form sent as PDF that you need to fill in neatly. An offer letter or a rental agreement draft where a few lines have to change. In all of these the original .docx is on someone else's laptop, and you have only the PDF.
- Resume: converts well. It is mostly paragraphs, headings and bullet points, which are exactly what can be inferred. Expect to redo the fonts and fix spacing in the two-column header.
- Government or college form: often converts badly. Forms are boxes, empty cells and labels placed by position, the hardest case for any converter. If you only need to fill in a few fields, typing on top of the PDF is usually easier than converting it.
- Agreement or letter: converts well as long as it was exported from Word, not scanned. Read the numbers and names in the result before you send it on.
For forms and small changes, the PDF editor here adds text, images and signatures directly onto the PDF, so nothing has to be rebuilt. When you need to change the existing wording itself, the article on editing text in a PDF goes through what works.
Why tables really come out wrong
Tables in PDFs very often have no ruling lines at all. Where lines do exist they are drawn on a different layer from the text, invisible to anything pulling the words out. That is why approaches built on finding the lines fail so often.
So position is what gets read: cells whose left edges stand in the same place across several lines are treated as a table. The method is weakest on empty cells. An empty cell leaves no trace in the file, so that row simply appears to have one cell fewer and everything after it shifts along by one.
Merged cells behave the same way. Your eye sees two cells joined; the file contains one piece of text sitting slightly further left than its neighbours.
A scanned PDF needs OCR first
A PDF produced by an office scanner is a single photograph per page. Your eyes see letters, the file contains none. No tool can extract text the source never contained.
Optical character recognition can manufacture text from the picture. But it guesses letters from their shapes, so it mixes in errors like reading a zero as the letter O. In a contract or a submitted form that kind of error is expensive. Asking the issuer for the original file is usually faster.
The PDF to Word tool on this site does not do OCR. Drop a scanned PDF on it and it tells you it cannot read text from images, rather than handing you an empty or invented document. If a phone scan of a certificate is all you have, the text has to be typed or run through OCR software somewhere else first, and then checked line by line.
In short
When choosing a converter, ask whether you can edit what comes out before asking how closely it matches. And when the result is imperfect, being able to tell a limit of the tool from a limit of the format saves you from swapping tools for nothing.
The PDF to Word tool on this site is built on the reasoning above: it rebuilds paragraphs and tables into a DOCX you can edit, places images and stamps in reading order, and does not imitate the exact layout. It runs in your browser, so the file stays on your device.
Common questions
- Why does my converted Word file look different?
- A PDF stores where each character is printed, not paragraphs, tables or Word styles. The converter has to infer those from positions, and things that were never recorded, such as styles, merged cells and exact spacing, cannot come back. Fonts are often replaced too.
- Can I convert a scanned PDF to Word?
- Not directly. A scanned page is a picture with no text in it, so it needs OCR first, and OCR makes mistakes such as reading 0 as O. The PDF to Word tool here does not do OCR. Ask for the original file if you can.
- Why do different converters give different results?
- Because their inference rules differ. How wide a gap counts as a paragraph break, how many aligned rows count as a table: every tool draws those lines somewhere slightly different. That is why one tool suits certain documents better than another.
- My tables keep coming out wrong. Is there anything I can do?
- The more empty cells a table has, the worse it fares, because an empty cell leaves no trace in the PDF. If it is only the table you need, converting to a spreadsheet beats converting to Word. The spreadsheet path snaps cells to columns deliberately, and misalignment is easier to repair by hand.
- The fonts changed.
- A PDF does embed font files, but there is no guarantee they carry the name the original document specified, and far less that the same font is installed on the machine opening the result. So fonts are left alone and the default is used.
- Is there a converter that does not upload my file?
- Yes, the tools on this site work that way. The whole conversion finishes inside the browser, so there is no upload step. To check, open the network tab in developer tools and run a conversion.
Last updated October 14, 2026 · Accurate as of October 2026. Tool behaviour follows the PDF to Word tool on this site as tested on 14 October 2026.